
Upvotes
0
Pricing
Open Source
Category
Coding Tools
In the database since
Oct 2026
Overview
About llama.cpp
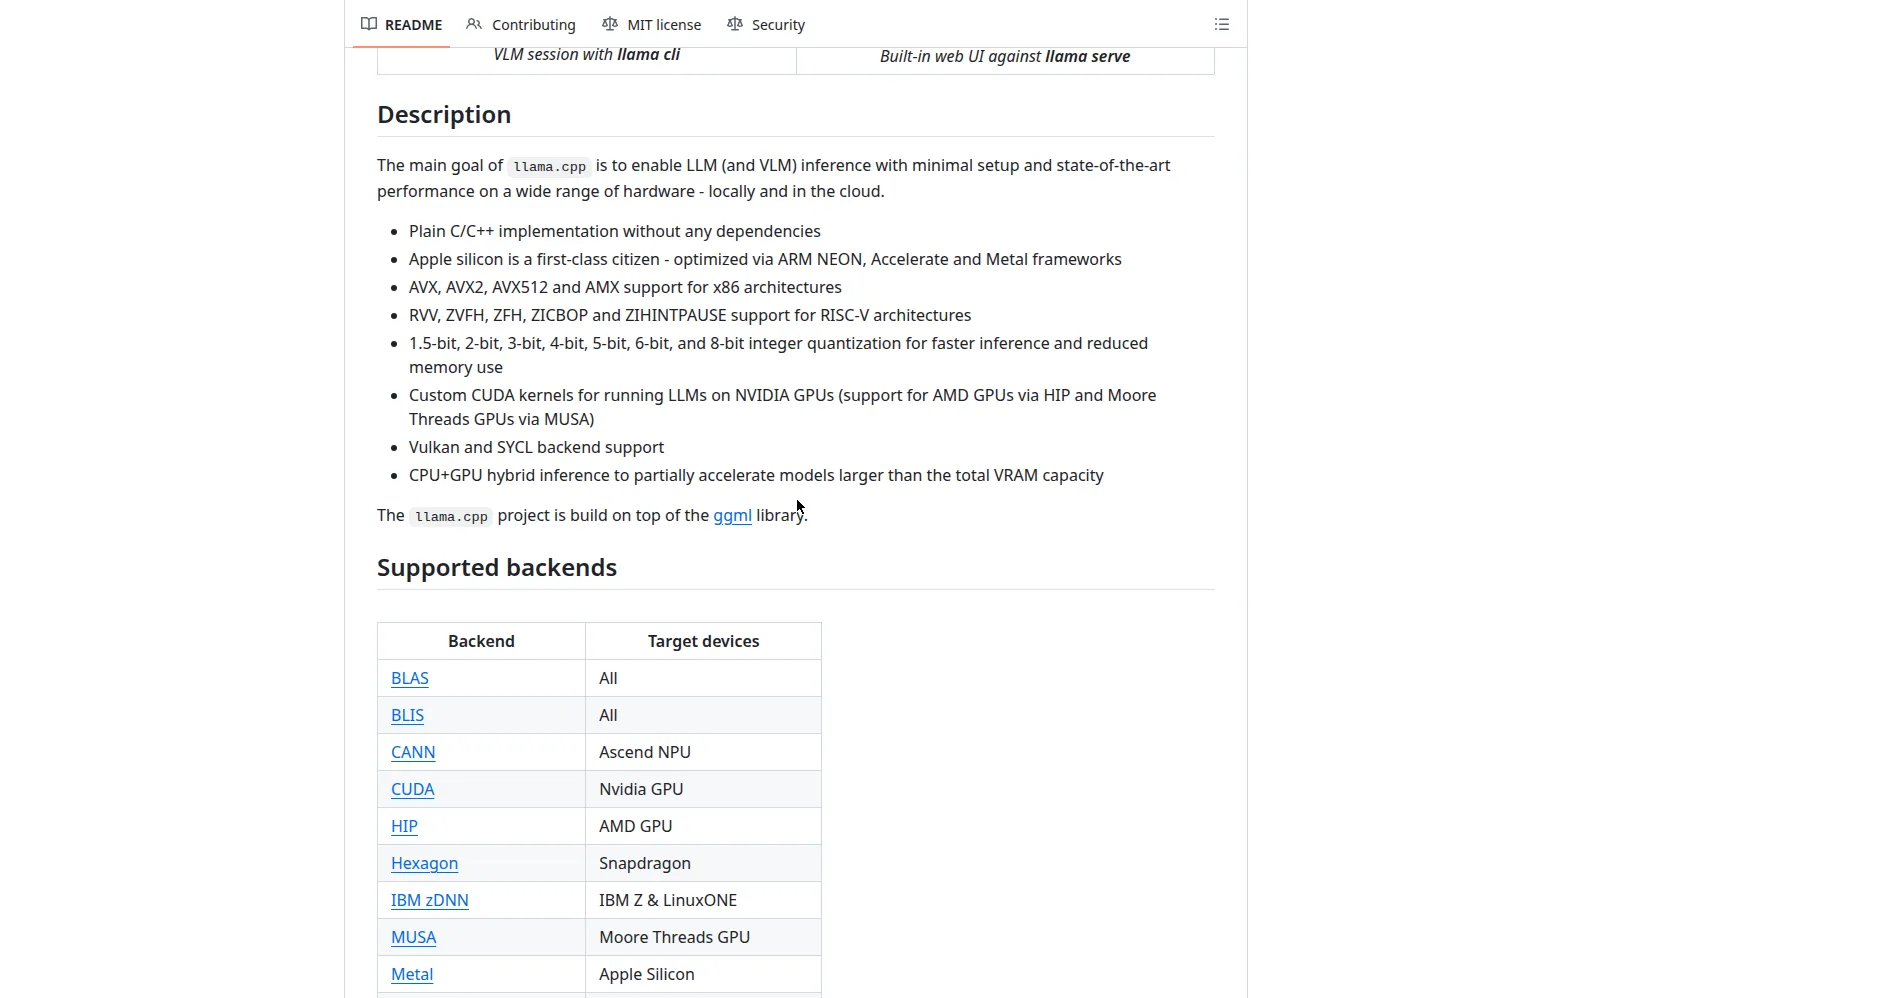
llama.cpp is a fast engine for running AI models on your own computer. It is written in C and C++ with no extra dependencies needed. The project works on Apple Silicon, NVIDIA, AMD, and regular CPUs. It can shrink models so they use less memory on your machine. A built-in server lets your apps use local models easily. Many popular tools like Ollama use it under the hood. You can run it on servers, laptops, and even phones.
Key Features
1. Fast Engine
Runs models quickly on many types of hardware. Written in C for top speed and low memory use.
2. No Dependencies
Works without installing extra software. Just build and run it on your machine. A single code base keeps setup simple.
3. Wide Support
Runs on Mac, Windows, Linux, and phones. It supports many chip types, with extra speed from GPU backends.
4. Model Shrinking
Makes models smaller so they fit in memory. You can run big models on small machines.
5. App Server
Includes a server for your apps to call. Works like the OpenAI API format. It ships with a built-in web UI too.
Frequently Asked Questions (FAQ)
What is llama.cpp?
It is an engine for running AI models locally. It is fast and needs no extra setup.
Which models work?
Many open models like Llama and Mistral. Check the docs for the current list.
Do I need a GPU?
No, but it helps. It runs on CPUs too, just slower than on GPUs.
Is it hard to use?
Basic use is simple with clear commands. Advanced tuning takes some learning.
What tools use it?
Ollama and many apps build on it. It is the engine behind lots of local AI.
Conclusion
llama.cpp powers local AI for developers worldwide. The fast engine runs models on almost any hardware. No dependencies means simple setup everywhere. Model shrinking fits big models on small machines. It suits anyone building local AI apps or tools. The open code keeps improving with every release. It remains the top choice for local model inference.
Keep exploring
Similar AI tools
Ranked by the job they do, their capabilities, and how closely they fit this workflow.