Upvotes
0
Pricing
Open Source
Category
Research
In the database since
Oct 2026
Overview
About LLaVA
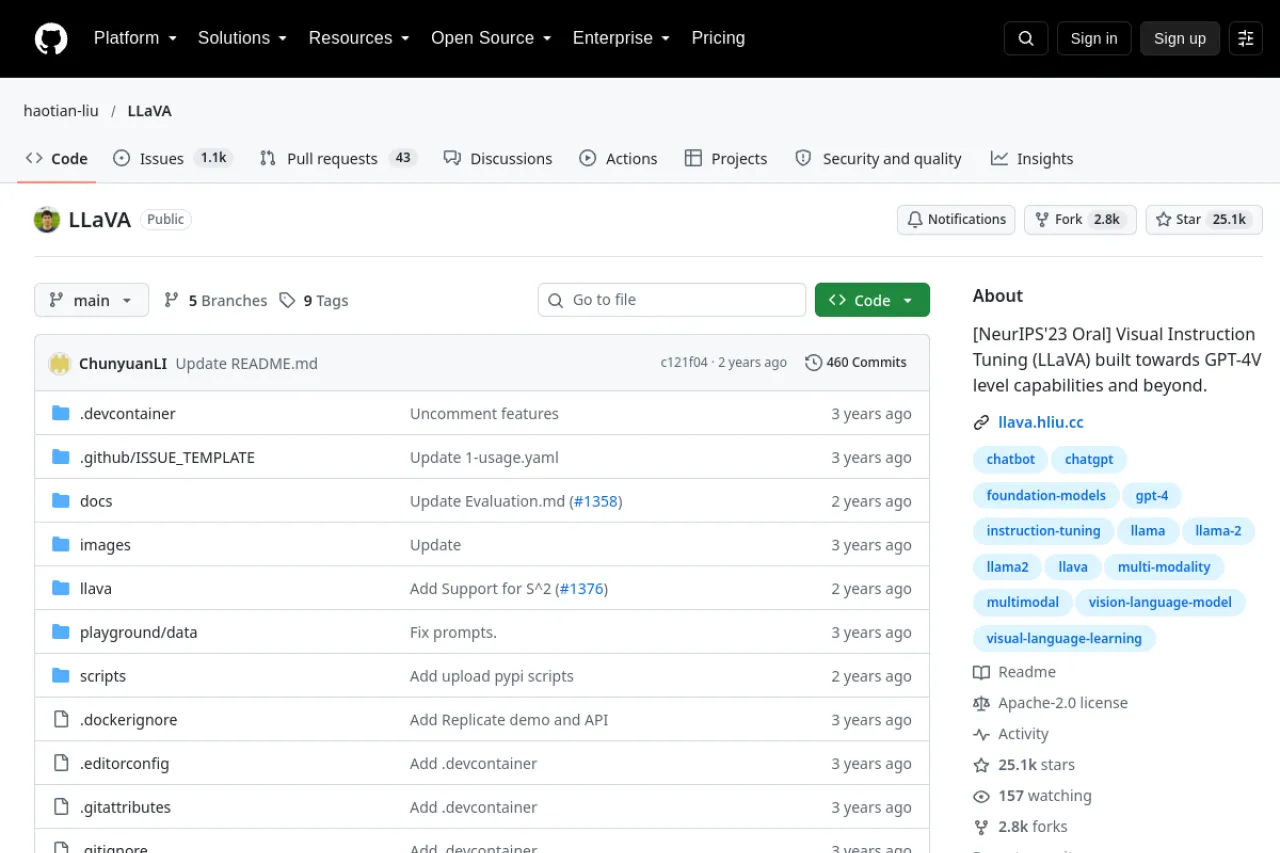
LLaVA is an open-source large language and vision assistant. You show it an image and ask questions, and it answers about what it sees in plain words. It was built with visual instruction tuning, which teaches the model to follow image-based tasks. The project showed strong results on vision-language tests when it launched. It is made for researchers and developers building apps that mix images and text. The code and models are open under the Apache 2.0 license. Check the official GitHub repo and project page for the demo.
Key Features
1. Image Q&A
Upload a photo and ask anything about it, from objects in view to text on signs.
2. Visual instruction tuning
The model is trained to follow image tasks closely, not just name what it sees.
3. Open models
The trained models are openly shared, so researchers can test them and build on them.
4. Live demo
An online demo lets you try image chats right away without installing anything on your computer.
5. Research code
The repo shares training code and data notes, so other teams can repeat the work.
Frequently Asked Questions (FAQ)
What is LLaVA used for?
Researchers use it to chat about images and to study vision-language AI. Developers build image Q&A features on its open models.
What does visual instruction tuning mean?
It means training the model on image tasks with written instructions. The model learns to answer image questions in a helpful way.
Can it read text in images?
Yes. It can read signs, labels, and simple documents in photos, then answer questions about what the text says.
Is LLaVA the newest vision model?
No. It was a breakthrough at launch, and newer versions like LLaVA-NeXT followed. Check the project page for the latest release.
Can I use it commercially?
The Apache 2.0 license allows commercial use. Read the license on GitHub for the exact terms.
Conclusion
LLaVA helped prove that open models can chat about images well. It suits researchers and developers working on vision-language apps who want open code and models. Try the online demo before you install anything. Newer versions may suit new projects better. Check the official GitHub repo and project page for models, code, and the latest version.
Keep exploring
Similar AI tools
Ranked by the job they do, their capabilities, and how closely they fit this workflow.